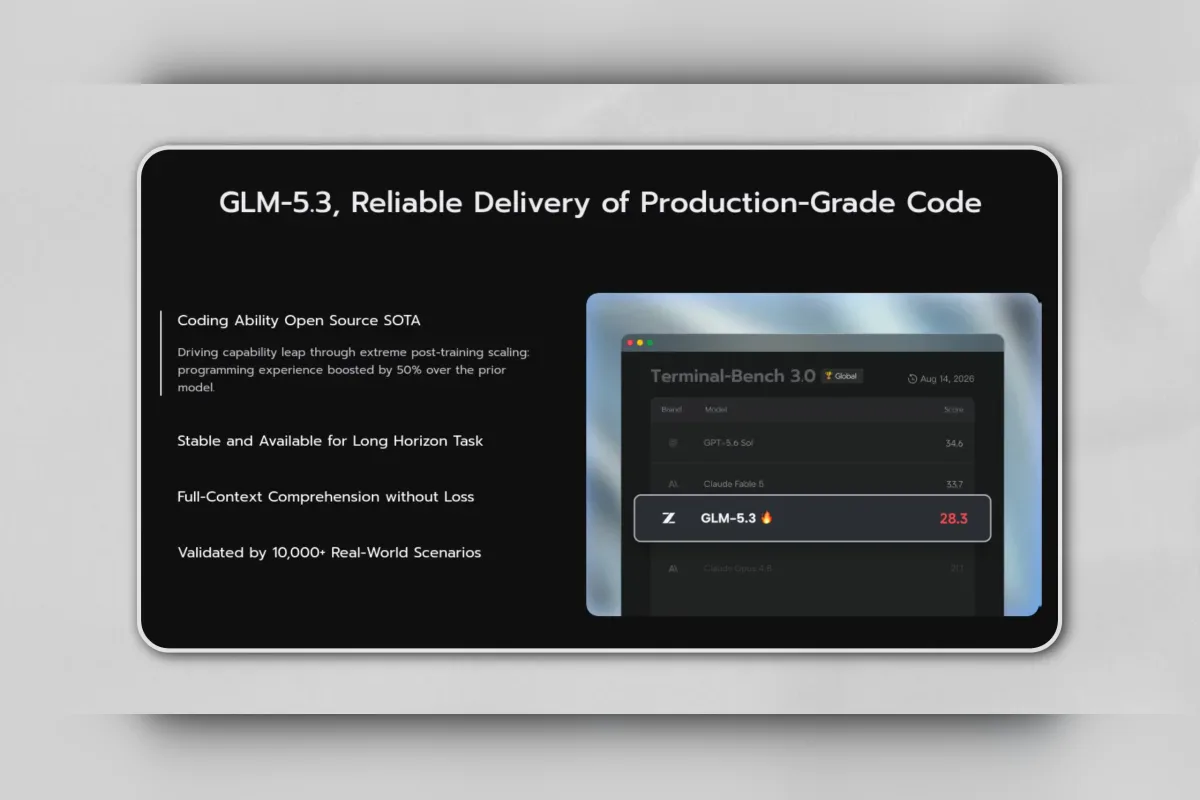
On August 14, Z.ai, the Chinese developer of the GLM models, officially launched GLM-5.3. The most notable aspect of this upgrade is that it shares the same base model as GLM-5.2, with all improvements stemming from scaling up the post-training phase—specifically reinforcement learning (RL) running on the long-horizon infrastructure that Z.ai has built across previous versions.
In terms of programming, Z.ai claims GLM-5.3 is currently the strongest open-weights model, showing a nearly 50% improvement over GLM-5.2 on its internal benchmark, Z.ai Code Bench. On public benchmarks, the model achieved SOTA (state-of-the-art) among open-source models on Terminal Bench 3.0 (jumping from 4.6 to 28.3 points) and Agents’ Last Exam. A particular advantage is token efficiency: at high effort levels, GLM-5.3 reached 31.4% with only about 50K output tokens, surpassing Claude Opus 4.8 (29.5% with nearly 120K tokens). Even so, it still trails Claude Fable 5 on the most challenging tests.
The most striking and controversial feature of GLM-5.3 lies in what Z.ai calls an “emergent cyber capability.” They incorporated vulnerability research data into the training process, and the results far exceeded expectations: the model not only identifies individual bugs but also constructs complete exploit chains. On the CyberGym benchmark, GLM-5.3 achieved 84.5%, leading both Fable 5 (83.8%) and GPT-5.6 Sol (83.6%). However, higher up the exploit chain, the gap with closed models widens—on ExploitBench, GLM-5.3 doubled its score (from 24.4 to 54.4) but still falls well short of Fable 5 (78%) and GPT-5.6 Sol (76.5%).
Beyond benchmarks, Z.ai stated that it collaborated with several security teams in China to run the model on real-world codebases, discovering 2,436 vulnerabilities across 269 projects, including 1,097 medium-to-high severity flaws. Many of these vulnerabilities had existed for decades, with one originating in 1981. For transparency, the company created the public Z.ai Security Disclosure Ledger to track the disclosure process for these flaws. Currently, 53 vulnerabilities have been disclosed, while the remainder remain under embargo.
Regarding openness, Z.ai has committed to releasing the model weights approximately two weeks after launch, once safety evaluations and hardening are complete. This also presents a key point to consider: publicly releasing an open-weights model with such potent exploit capabilities represents both scientific progress and a security risk that requires close monitoring.
Overall, GLM-5.3 shows that Z.ai’s strategy of “simply scaling post-training” is paying off in programming, though a clear gap remains compared to top closed models on the most demanding tasks.