On August 26, Z.AI (the Chinese AI lab also known as Zhipu) officially confirmed the identity of GLM 5.3 Flash, an AI model that had been tested anonymously for nearly a week under the name Ox Alpha and quietly climbed to the top of the usage leaderboard on OpenRouter, surpassing even DeepSeek in real user volume.
Prior to its official launch, Z.AI deployed GLM 5.3 Flash for free on OpenCode and OpenRouter under the alias “ox-alpha” without disclosing its identity. In less than a week, the model became the most popular choice on OpenRouter, with usage twice as high as DeepSeek. Stripe CEO Patrick Collison commented “very impressive” on social media after trying out the model.
Previously, the user community had also analyzed the output and tokenization of Ox Alpha, noting that the model’s characteristics closely resembled the GLM-5 architecture and guessing that it was a checkpoint from the GLM-5.3 family. Just a few days later, on August 26, Zhipu confirmed to Bloomberg that Ox Alpha was indeed the GLM 5.3 Flash preview, while also announcing that it would open-source the weights following the official launch.
GLM 5.3 Flash is the first model in the GLM-5 series to natively support multimodality (text, images, video) with a context window of 1.3 million tokens, serving well for long-document processing workloads or multi-turn conversations with large repeated context. Notable architectural highlights include:
-
320B total parameters, with only 18B active parameters, nearly half that of GLM-4.5/5.x (32B active), enabling significantly faster inference speeds.
-
A hybrid attention architecture combining linear attention (handling local dependencies) with sparse attention (retrieving global context)—optimized by the IndexPool mechanism, reducing attention compute by 3× and KV cache size by 4.4× compared to standard GLM-5.3.
-
Pre-trained on 30 trillion multimodal tokens.
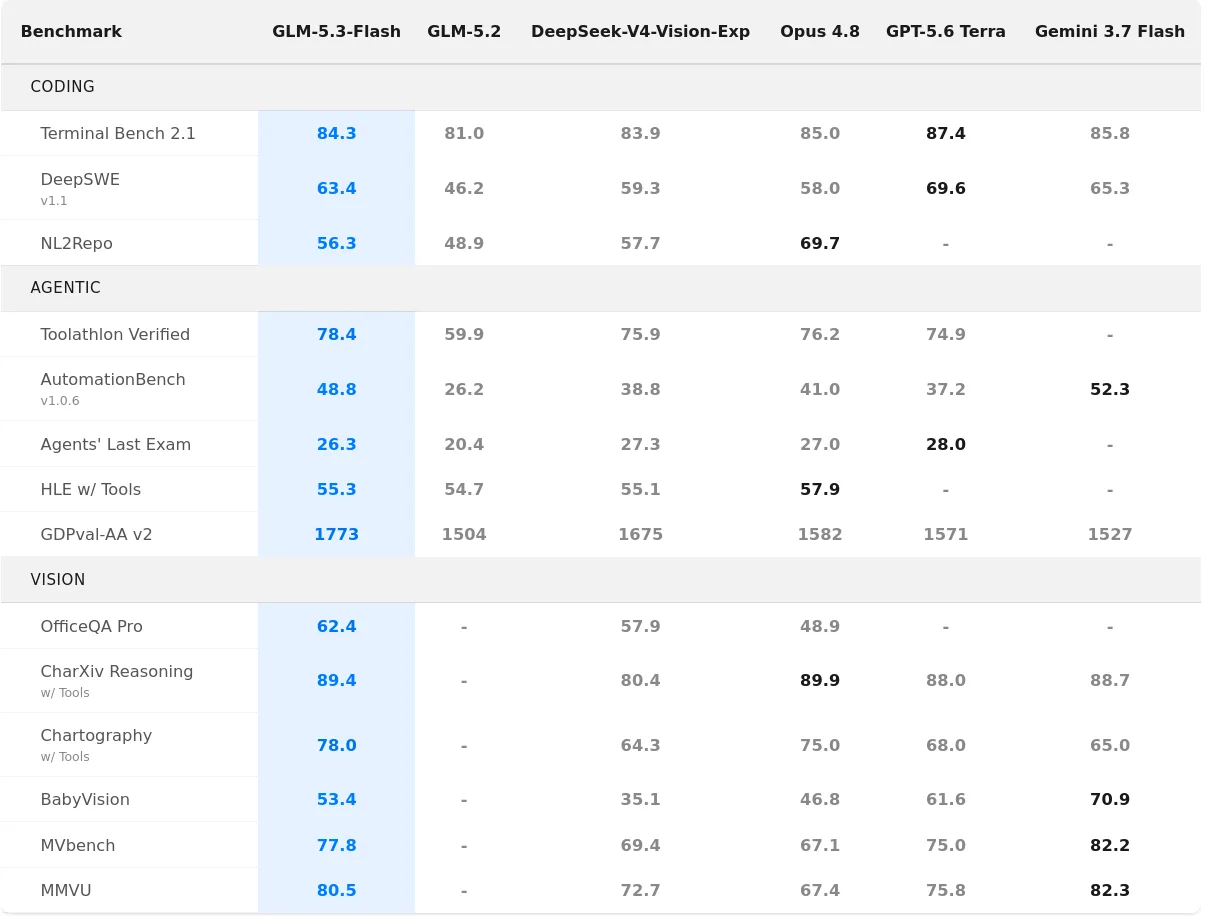
In terms of benchmarks, GLM 5.3 Flash scored 63.4 points on DeepSWE v1.1 (compared to 46.2 for GLM-5.2) and 48.8 points on AutomationBench v1.0.6 (compared to 26.2). On Z.ai Code Bench v1.0, the model achieved 29.0 points, nearly on par with Claude Opus 4.8 at 29.5.
Regarding API pricing, GLM 5.3 Flash is priced per 1 million context tokens as follows:
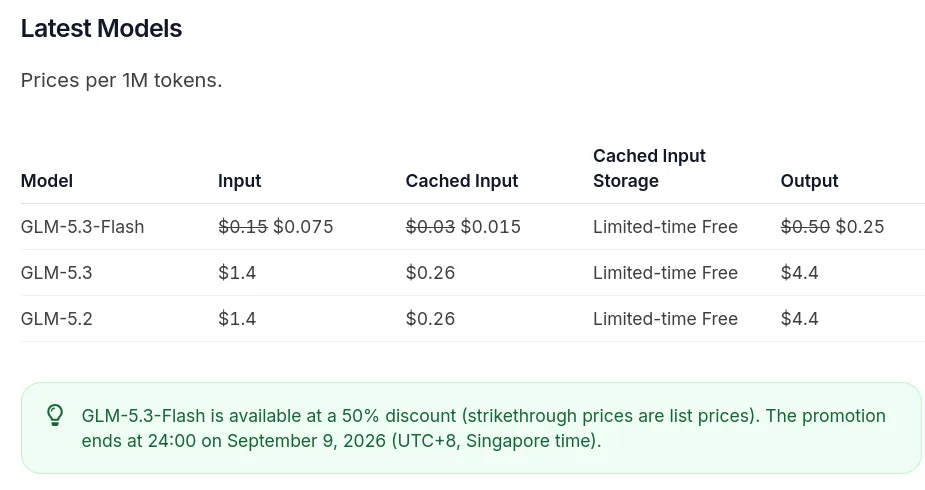
- Input: 0.15 USD/M tokens
- Output: 0.50 USD/M tokens
- Cached input: 0.03/M tokens
At standard pricing, GLM 5.3 Flash is about 9 times cheaper than GLM-5.2 based on output tokens. In addition, Z.AI announced a 50% discount for this model through September 9, 2026.
Another notable point is that Z.AI runs the GLM 5.3 series on a large-scale cluster of Chinese domestic AI chips without using NVIDIA GPUs. The company stated that it achieved a 3-fold improvement in end-to-end performance over the initial baseline through techniques such as EPD disaggregated architecture, W8A8 quantization, and hybrid cache. This is one of the few public demonstrations that domestic AI chips can run frontier models at practical scale.
In summary, GLM 5.3 Flash stands out with its unconventional launch strategy of anonymous real-world testing prior to announcement, and the results achieved on OpenRouter demonstrate genuine user interest. Z.AI said it is scaling this architectural recipe to larger models in the coming time.